Skip to content
Back to Ideas 1 min read

Stage, Then Transform: Crawlers Stay Out of Production

Stage, Then Transform: Crawlers Stay Out of Production

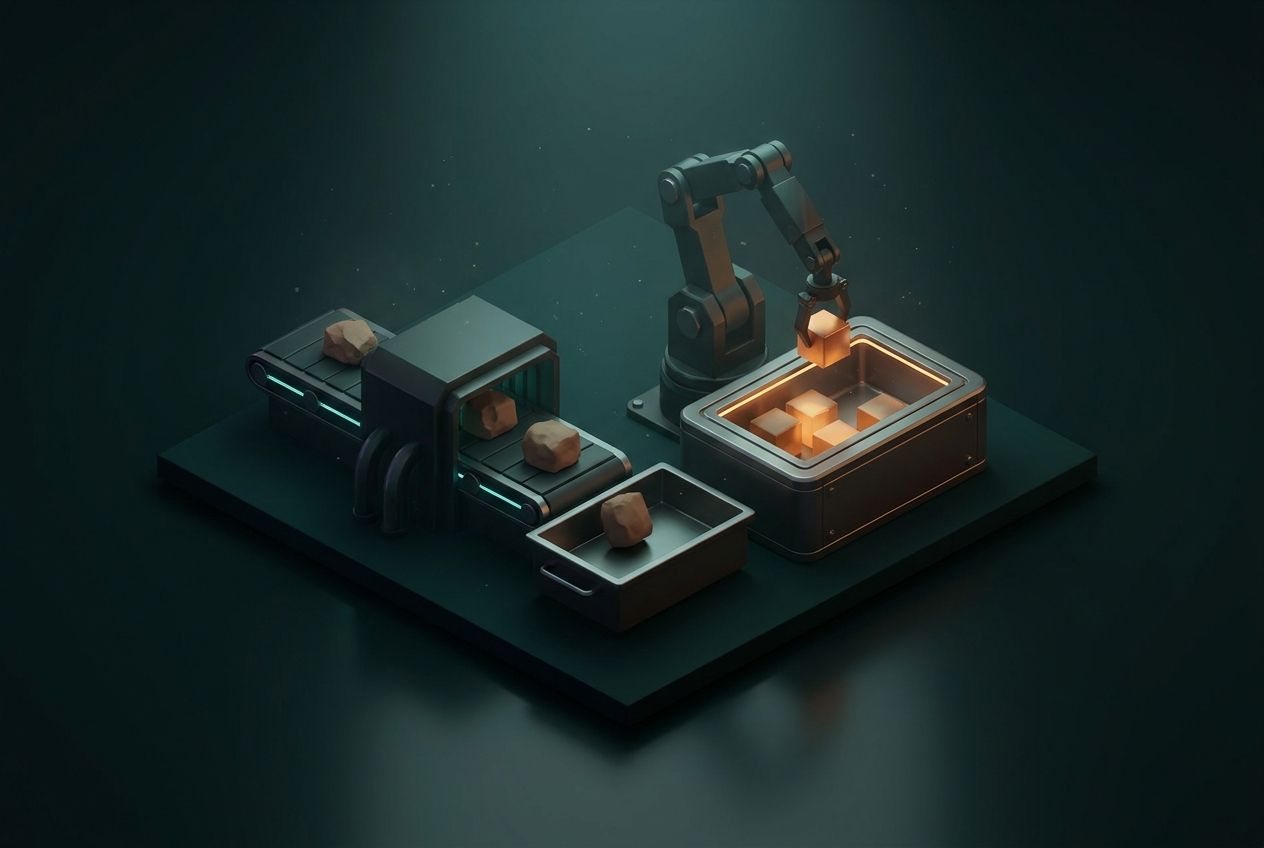
When you pull data from an external source, a public register, a CSV feed, a scraped site, there is one decision that quietly determines whether the pipeline will still be working in six months. It is not “which library”, “which schedule”, or “which database”. It is: where does the data land first?

Most pipelines answer that question badly. They crawl a source, massage the rows in-memory, and write straight into the production table the app already reads from. It works on day one. It breaks on day ninety.

This post is the pattern I wish I had internalised before I wrote my first crawler, explained with the pipeline we are building right now at Propi: matching first-time buyers to UK conveyancers using public SRA and Law Society data.
The shortcut that bites

More from Ideas

·8 min read

Inversion of Control Doesn't Need a DI Container

We started designing a dependency scanner, and its needs led us to Inversion of Control. It turned out we were already doing it, without a DI container.

A
Anastasios Orfanidis
·7 min read

Unknown Is an Answer

A stub that holds no documents could not say whether a change still matched a query. Letting it answer unknown named a case the real database has too.

·7 min read

The Inbox That Delivers Nowhere

Signing in by emailed code puts a mailbox on the critical path. How we use Mailpit on Studomia, how our tests read the code, and what one question taught us.